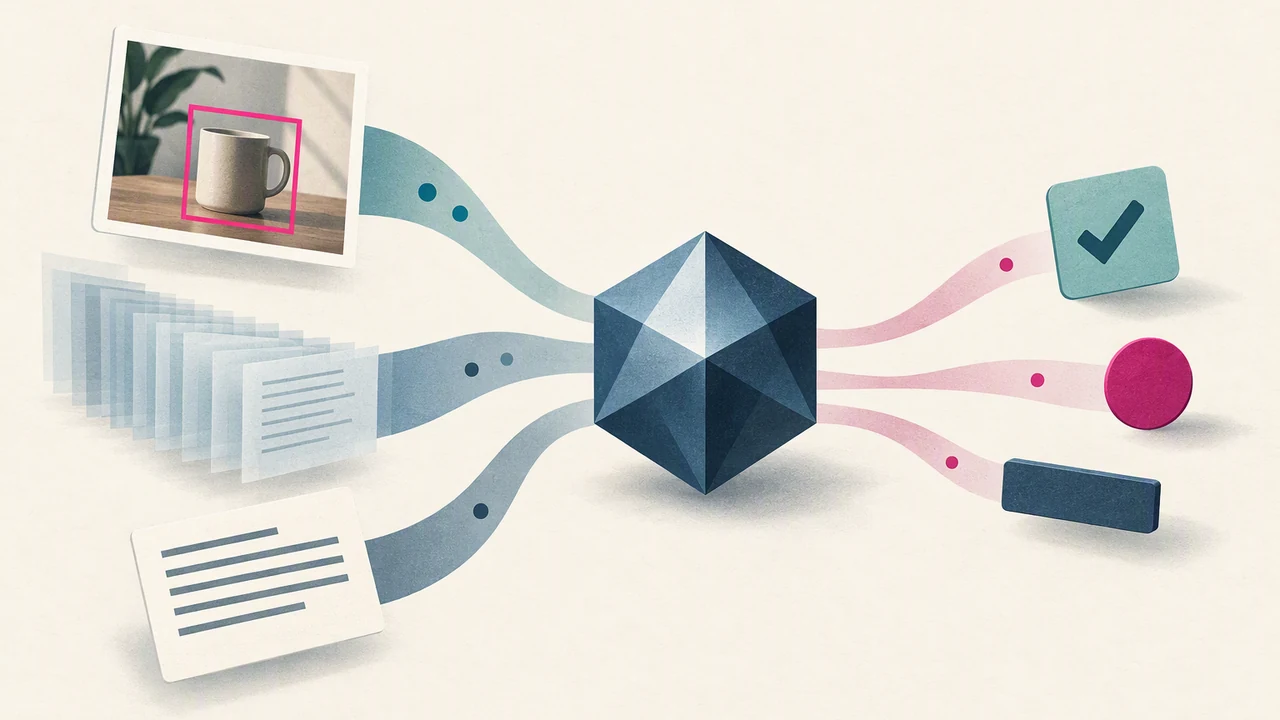
Jev 1.14 is the newest release of TypeSafe AI’s Jev, the decision model that returns typed answers (a choice, a score, a yes/no probability) instead of generated text. TypeSafe announced it on October 14, 2026, “at 1:14pm PT,” and made it available as jev-1.14.0 through the jev-preview alias and on OpenRouter as typesafe/jev-1.14.
This release has two parts. The model update itself is, in OpenRouter’s summary of TypeSafe’s own words, “beautifully boring”: a little better everywhere, with the biggest gain expected in multilingual support. The larger practical change is three experimental features behind opt-in headers: image input, a new Box answer type that locates something in an image, and a 262K-token context. This article stays on those 1.14 changes, then checks the first measurements from TypeSafe, Artificial Analysis, an enterprise field test, and a rival that launched one day later.
TL;DR
- Model:
jev-1.14.0brings “small, subtle improvements” with the largest expected gain in multilingual support. Price is unchanged: $0.042 per million input tokens, output free. - Images: images can go anywhere text can go in a request. They work on Jev 1.13 too, behind
TypeSafe-Danger-Zone-Images: true. - Box: a new question type returns one bounding box plus confidence. It requires Jev 1.14.
- Context:
TypeSafe-Danger-Zone-Long-Context: trueraises the limits from 64K/32K to 262K tokens, on 1.13 and 1.14. - Early results: TypeSafe’s internal chart shows a small gain (60.0 vs 58.9). Artificial Analysis has 1.14 at 57.07 and 1.13 at 57.50. One enterprise workflow passed 100% of runs on 1.13 and 93.6% on the 1.14 preview.
- Timing:
jev-lateststill pointed to 1.13.0 on October 16 and was scheduled to move about a week after launch.
The Jev 1.14 changelog in one table
| Jev 1.13 (before) | Jev 1.14 (now) | How you turn it on | |
|---|---|---|---|
| Model | jev-1.13.0 via jev-latest | jev-1.14.0 via jev-preview | Set model |
| Input | Text by default | Text by default | — |
| Image input | Available now, preview | Available, preview | TypeSafe-Danger-Zone-Images: true |
| Box question type | Not available | Available, preview | Same images header |
| Context | 64K per request / 32K per question; 262K opt-in | Same | TypeSafe-Danger-Zone-Long-Context: true |
| Price | $0.042 / M input, output free | Unchanged | — |
| Deprecation notice | 60 days before deprecation | 30 days before deprecation | — |
Two details matter for upgrade planning. First, much of what looks “new in 1.14” also works on 1.13: TypeSafe says the earlier model “was multimodal all along,” and long context is a limit TypeSafe chose to enforce rather than a capability 1.13 lacked. Only Box is exclusive to 1.14. Second, nothing changes unless you opt in. The new model only answers when you send jev-preview or jev-1.14.0, and each preview needs its own header on each request.

Figure 1. Where the 1.14 changes plug in. Preview headers gate images, Box, and long context; the model field and alias decide which Jev version answers; your code still decides what to do with the typed result.
Why the new features sit behind a danger-zone gate
TypeSafe framed the release as a split between two audiences. CEO Diogo Almeida put it this way on launch day: “The needs of early adopters / tinkerers / dreamers are quite different from what is needed for extremely stable infrastructure. For the Jev release, we erred on the latter, but this release is for the former - with a gate so people can opt-in to the danger zone!”
The launch post describes the gate as “danger zone” flags in the API headers. The features are meant to stay for future models, but TypeSafe says “there is still way too much jaggedness for us to vouch for these for production use cases.” The documentation repeats the warning: request formats, answers, and limits “can change between releases.”
In a podcast clip TypeSafe shared on October 16, Almeida frames the reliability problem this way: “if AI responds like Einstein 95% of the time and Mr. Bean 5% of the time, how are you going to automate anything with it?” The danger-zone gate is TypeSafe’s own signal that these new capabilities are not yet at that reliability bar.
Distribution still moved quickly. OpenRouter listed Jev 1.14 the same day, and Databricks’ Yuchen Jin posted that the company is “excited to partner with TypeSafe to bring the new Jev to our customers.”
New: image input, on 1.13 and 1.14
 Figure 2. TypeSafe’s launch graphic for image input (“Jev got eyes”), from the announcement thread.
“Composable images” is the headline feature. Each image is listed once in a top-level assets map under a reference string, and you place that reference wherever the image belongs: in the state, inside a question’s instructions, or inside the criteria that define an option. The API swaps the reference for the image before the model reads it. That makes three patterns possible in one request:
- Judge an image: the photo sits in the state, and every question sees it.
- Compare against a known image: “Is the person in
doorthe same person as in this badge photo?” - Define options by example: a Choice option such as
thumbs_upcan be a picture instead of a sentence.

Figure 3. One image reference each in the state, a question’s instructions, and a Choice option. Source: TypeSafe’s images documentation. On narrow screens, the diagram is redrawn from the same example.
The documented limits are strict, and the API rejects rather than resizes. Images must be still PNG or JPEG files, at most 16 MiB each, between 280 and 1,568 pixels per side and between 78,400 and 2,458,624 total pixels. The request body and the expanded request (after every reference becomes an image) are each capped at 32 MiB, and every repeated reference counts again. A request without the header, or with an unreferenced asset, returns 400. The API also strips metadata and ignores EXIF orientation, so phone photos need their pixels rotated before upload.
Images are billed as ordinary input tokens at the text price. TypeSafe has not yet published how many tokens an image costs. Its launch post adds the key caveat: all models, Jev included, perform worse on images than on pure text, and breaking a question into the simplest possible parts helps.
New: Box, a bounding-box answer type
Box is the only feature that requires the new model. TypeSafe’s thread called it proof that “machine-native types go far, far beyond just decisions”: instead of picking an option, a Box question returns where something is.
A Box question has two fields, type: "box" and instructions such as “the coffee mug in photo.” The answer is four edges (top, bottom, left, right) as fractions of the image size, measured from the top-left corner, plus a confidence from 0 to 1.

Figure 4. A Box answer: four fractional edges that work at any image size. Source: TypeSafe’s Box documentation and launch thread. On narrow screens, the diagram is redrawn from the same values.
Three design choices matter in practice:
- There is no “not found.” A Box question about something absent still returns four edges. TypeSafe recommends asking a Noul (“Is there a coffee mug in
photo?”) in the same request and ignoring the box when that probability is low. - One box per question. Several targets need several Box questions. If the image may contain several copies of the same thing, describe the one you want or add a Choice with
none,one, andseveral. - Small targets need a crop. A target a few dozen pixels wide in a large image can be missed. TypeSafe suggests finding the region first, for example with a Choice whose options are image tiles.
TypeSafe also documents a way to check a box: crop to it and ask one Noul per edge, such as “Does the mug continue past the left edge?” On 36 painting crops with part of the target cut off, the four edge questions caught 30 of the cuts. A single “Is all of the mug inside the crop?” question caught 26, and drawing the box on the full image caught 20. That is a small vendor test, not a general accuracy figure, but it shows the intended style: several small, checkable questions rather than one trusted answer.

Figure 5. A defensive Box pattern assembled from TypeSafe’s documentation. Thresholds are yours to tune; TypeSafe does not recommend one yet.
For comparison, MarkTechPost’s launch coverage notes that a general model such as Gemini 3.5 Flash-Lite returns boxes through prompted JSON on a 0–1000 scale, while Jev returns them as a native typed answer on 0–1 fractions.
New: 262K context on request
“Size does matter, apparently,” TypeSafe posted. “While we strongly recommend limiting context length, you no longer have to. Jev can take it. 4 times as much of it.”
Each request has two limits. The per-request context covers the state plus all questions; the per-question context covers the state plus any one question. By default they are 64K and 32K tokens. With TypeSafe-Danger-Zone-Long-Context: true, both become 262K, on Jev 1.13 or 1.14. OpenRouter lists typesafe/jev-1.14 with a 262K context.
TypeSafe says Jev always supported longer inputs and that it capped them on purpose, because Jev, like all models, is less reliable on long contexts. The models page is explicit that long-context requests cost the same per token but are “slower and less accurate than staying within the default limits.” The practical use is narrow: keep the default for routing and classification, and send the header only for a question that genuinely needs a whole long document, such as whether a contract contains an early-termination clause.
The model itself: what the first measurements say
TypeSafe usually avoids public benchmarks. For this release it published internal charts, with unusually blunt caveats: the measurement “will continue to evolve,” readers should “always favor your own experimentation,” only open-weight models are compared, and the result “is likely biased towards our models.” Each chart carries the banner “Please don’t trust them.”

Figure 6. TypeSafe’s internal “overall intelligence” score: Jev 1.14.0 at 60.0, 1.13.0 at 58.9. Source: TypeSafe’s launch post, self-reported. On narrow screens, the chart is redrawn from the same values.

Figure 7. TypeSafe’s internal calibration error, lower is better: 1.6 for Jev 1.14.0, 1.8 for 1.13.0. Source: TypeSafe’s launch post, self-reported. On narrow screens, the chart is redrawn from the same values.
Two outside measurements, published within two days, show a more mixed picture.
Artificial Analysis. The Artificial Analysis Decision Index combines four evaluations it runs independently: AA-Omniscience-Decision (knowledge and hallucination), HLE multiple choice (reasoning), When2Call (tool calling), and WildGuardTest (safety classification). When we checked on October 16, it scored Jev 1.14 at 57.07 and Jev 1.13 at 57.50. The components moved in both directions: 1.14 hallucinated less often but answered fewer HLE questions correctly.

Figure 8. Jev 1.13 versus Jev 1.14 on Artificial Analysis’s independent Decision Index and its components, charted by AgentsPulse from the values on Artificial Analysis’s page, accessed October 16, 2026.
Isotopes AI. Isotopes AI tested both versions inside an existing enterprise analytics workflow, where several decisions (source, metric, filters, dates) must all be right before an app answers a follow-up question. Across three runs of the same 88 scenarios, with a fixed 0.50 confidence threshold, Jev 1.13 passed 100% and the 1.14 preview passed 93.6%. Median decision-and-composition time was 0.807 seconds for 1.13 and 0.838 for 1.14. Isotopes is clear that these are repetitions of the same scenarios, not independent tasks, and that 1.14 was still a preview.
Taken together, the evidence supports a modest reading. On TypeSafe’s own validation set, 1.14 is slightly ahead. On one independent index it is flat to slightly behind, and in one real workflow it was a little less reliable. None of these sources measured the multilingual gain TypeSafe expects to be the biggest change, so teams with non-English workloads have the strongest reason to test it themselves.
A day later: Liquid AI’s d1-ultra targets Jev 1.14
The competitive context arrived quickly. On October 15, one day after Jev 1.14, Liquid AI released d1-ultra, which it calls “the world’s best decision model,” at the same $0.042 per million input tokens. IT Home summarized it as Liquid “overtaking” Jev 1.14 a day after launch. Microsoft’s entry, Microsoft-Decision-1, appears in both Liquid’s comparison and the Artificial Analysis index.

Figure 9. Liquid AI’s own comparison across eight task categories (112 evaluations). d1-ultra averages 76.7 and Jev 1.14 averages 69.4. Source: Liquid AI, vendor-reported. On narrow screens, the chart shows only the d1-ultra and Jev 1.14 columns, redrawn from the same values.
On Liquid’s suite, the narrowest gap is “Pictures” (77.9 versus 75.4), and the widest is “Judgment and taste” (65.5 versus 53.3). The independent Artificial Analysis index agrees on the direction: d1-ultra scores 65.25 there, against 57.07 for Jev 1.14. Liquid’s calibration chart, however, shows how strongly results can depend on evaluation setup.

Figure 10. Liquid AI’s calibration measurement, lower is better: d1-ultra 1.5, Jev 1.14 2.7. Source: Liquid AI, vendor-reported. On narrow screens, only the calibration-error bars are redrawn.
TypeSafe reports a calibration error of 1.6 for Jev 1.14 (Figure 7). Liquid reports 2.7 for the same model (Figure 10). Both can be honest because each vendor used its own evaluation set and metric. The practical takeaway is the one TypeSafe itself states: published calibration and accuracy numbers do not transfer directly to your workload, and thresholds tuned on one model version need re-tuning on the next.
Rollout: aliases, price, and deprecation
The alias plan is the part of the release most likely to affect production code without anyone noticing:
-
jev-preview→jev-1.14.0from launch. -
jev-latest→ stilljev-1.13.0when we checked TypeSafe’s models page on October 16. The launch post said it would move to 1.14.0 “in a week.” -
jev-1.13.0stays available. TypeSafe intends to give 60 days’ notice before formally deprecating it, 30 days forjev-1.14.0, and to publish a deprecation policy first.
Because jev-latest is also the default in TypeSafe’s client SDKs, unpinned code will switch versions when the alias moves. Each response includes the versioned model ID that answered, so logging it is the cheapest way to tell which version produced a decision. This matters most where Jev sits inside an agent loop, such as the browser agent in our Jev Ultrafast explainer, where a model change can affect every action the agent picks. Pricing does not change: $0.042 per million input tokens ($42 per billion), free output, the same price for long-context requests, and images billed as input tokens.
The release also adds an organization-level opt-in, “Help improve TypeSafe models,” that lets TypeSafe read and analyze an organization’s inputs and outputs to find model jaggedness. TypeSafe says it still does not train on customer queries.
Should you move to jev-preview now?
| If you… | Reasonable move |
|---|---|
| Run Jev in production with tuned thresholds | Pin jev-1.13.0, rerun your evals on jev-1.14.0, and switch deliberately before jev-latest moves |
| Route or classify non-English text | Test 1.14 first; multilingual is TypeSafe’s expected biggest gain, but no published test has measured it yet |
| Want image triage, visual checks, or UI grounding | Try images and Box behind the header, pair Box with a presence Noul, and keep a fallback |
| Classify whole long documents | Use long context only for those requests and compare against chunked 64K requests |
| Are choosing a decision-model vendor | Include d1-ultra in the bake-off; it costs the same per input token and leads on the independent AA index |
The case for waiting is TypeSafe’s own wording about the previews. The case for testing now is that every change is opt-in per request, so you can evaluate 1.14 side by side with 1.13 without touching production traffic.
Try the new features in one request
This adapts TypeSafe’s documented example. It sends one image as a multipart file, enables the images header, targets jev-preview, and pairs a presence check with a Box question:
curl https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "TypeSafe-Danger-Zone-Images: true" \
  -F 'request={
    "model": "jev-preview",
    "state": {"photo": "6e1d0b7c-kitchen"},
    "assets": {"6e1d0b7c-kitchen": {"type": "image", "part": "kitchen-photo"}},
    "questions": {
      "mug_visible": {"type": "noul", "instructions": "Is there a coffee mug in `photo`?"},
      "mug": {"type": "box", "instructions": "the coffee mug in `photo`"}
    }
  };type=application/json' \
  -F 'kitchen-photo=@kitchen.jpg;type=image/jpeg'
Then act in code:
from PIL import Image

answers = response["answers"]
if answers["mug_visible"]["noul"] >= 0.5:          # tune for your cost of error
    edges = answers["mug"]["box"]
    image = Image.open("kitchen.jpg")
    w, h = image.size
    crop = (round(edges["left"] * w), round(edges["top"] * h),
            round(edges["right"] * w), round(edges["bottom"] * h))
    image.crop(crop).save("mug.jpg")
To try long context instead, send TypeSafe-Danger-Zone-Long-Context: true with a long state and a single whole-document question. In both cases, log the response’s model field so you know which version answered.
Jev 1.14 FAQ
What’s new in Jev 1.14?
Jev 1.14 (jev-1.14.0) is a small general model update with the largest expected gain in multilingual support, plus three opt-in previews: image input, a Box question type that returns a bounding box, and a 262K-token context window. Images and long context also work on Jev 1.13; Box requires Jev 1.14.
Is Jev 1.14 better than Jev 1.13?
Not clearly yet. TypeSafe’s internal chart shows 60.0 versus 58.9, but Artificial Analysis scores Jev 1.14 at 57.07 and Jev 1.13 at 57.50, and an Isotopes AI workflow test passed 93.6% of runs on the 1.14 preview versus 100% on 1.13. Test it on your own workload before switching.
Does jev-latest point to Jev 1.14?
Not at launch. jev-preview points to jev-1.14.0, and jev-latest still pointed to jev-1.13.0 on October 16, 2026. TypeSafe said jev-latest would move to 1.14.0 about a week after release.
Does Jev 1.14 cost more than Jev 1.13?
No. Both cost $0.042 per million input tokens with free output. Long-context requests and image tokens are billed at the same per-token input price.
How does Jev 1.14 compare with Liquid AI’s d1-ultra?
Liquid AI, which released d1-ultra a day after Jev 1.14, reports higher scores in all eight categories of its own 112-evaluation suite, averaging 76.7 versus 69.4. On the independent Artificial Analysis Decision Index, d1-ultra scores 65.25 and Jev 1.14 scores 57.07. Both models cost $0.042 per million input tokens.
References
- TypeSafe AI. “Jev: For the builders AND dreamers.” October 14, 2026.
- TypeSafe AI on X: launch thread, images, Box, long context, jev-preview, and CEO interview clip. October 15–16, 2026.
- Diogo Almeida. Launch-day post. October 14, 2026.
- TypeSafe documentation: “Images,” “Box,” and “Models.” Accessed October 16, 2026.
- OpenRouter. “TypeSafe: Jev 1.14” and launch post. October 15, 2026.
- Yuchen Jin. Post on Databricks and Jev 1.14. October 14, 2026.
- Asif Razzaq. “TypeSafe AI Releases Jev 1.14 With Images, Box Type and 262k Context.” MarkTechPost.
- Artificial Analysis. “Artificial Analysis Decision Index.” Accessed October 16, 2026.
- Prasanth Jayachandran. “Decision Models.” Isotopes AI, October 15, 2026.
- Liquid AI. “d1-ultra: Introducing the World’s Best Decision Model.” October 15, 2026.
- IT Home. “TypeSafe AI 发布 Jev 1.14 决策模型仅一天,Liquid AI 便以 d1-ultra 全面超车.” October 16, 2026.
- AgentsPulse. “Jev Ultrafast Explained” and “Microsoft-Decision-1: A Decision Model, Not a Chatbot.”